Scorer catalog
Every published Noveum scorer, what it checks, its scale, and whether it costs credits. Generated from the public product catalog.
A scorer is one named quality check. You select compatible scorers for an eval job; each scorer attempts the eligible items in the run and records either its result or an execution error.
The product directory publishes 112 scorers across 15 categories.
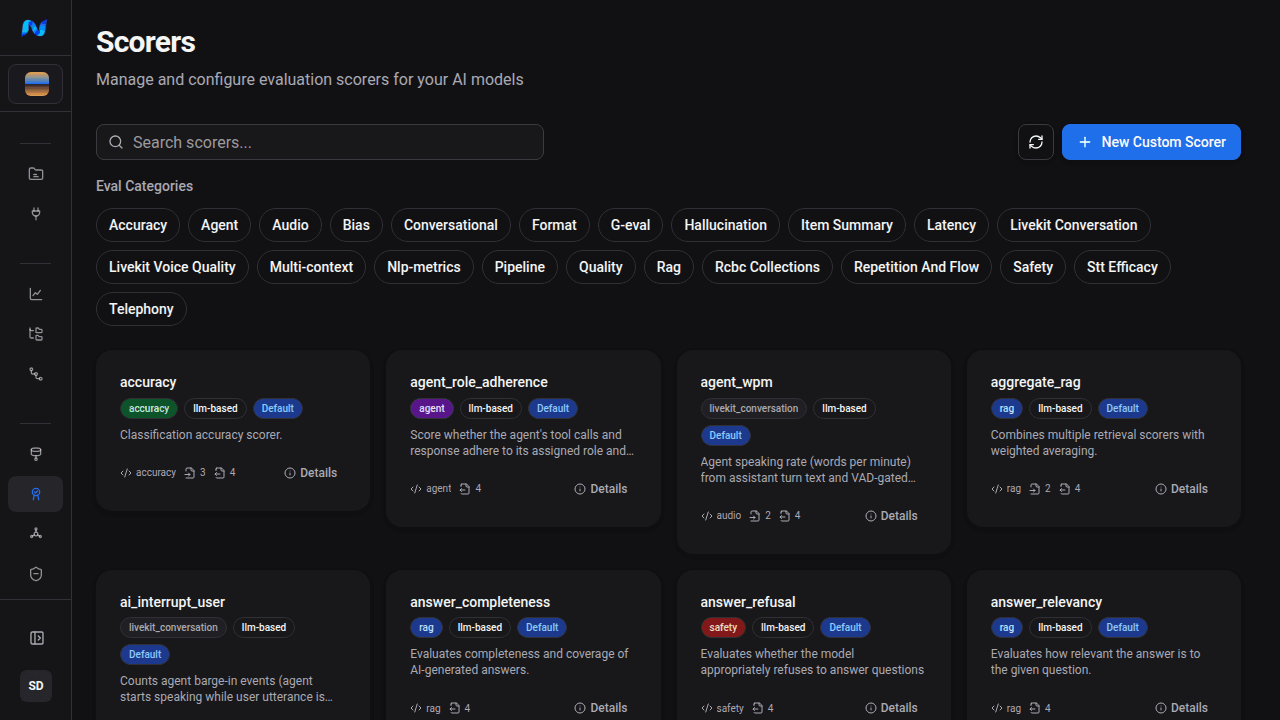
Scorer details open in a resizable, non-modal sheet. Drag its left edge, or focus the resize handle and use the arrow keys, while leaving the directory available underneath. The browser remembers the selected width.
This page is generated from the same public catalog as the scorer library. Your organization can also contain private custom scorers. The UI uses finer-grained tag filters - such as LiveKit Conversation, LiveKit Voice Quality, Repetition and Flow, and STT Efficacy - so the number of filter chips is larger than the number of catalog categories.
Before you choose a scorer
Define the evaluation question, inspect representative dataset-item JSON, and identify the evidence available to answer it. Use the catalog to compare checks; use Using scorers for configuration and compatibility guidance.
How to read this page
Scales are scorer-specific. The current catalog includes 0-10, 1-10, audio-derived 0-10, and millisecond-to-score transforms. Many 0-10 scorers use a default pass threshold of 7, but the saved scorer configuration determines pass or fail. Confirm the published scale and configured threshold before comparing or averaging different checks.
Two scores mean "no answer" rather than "bad answer":
-1- the scorer could not run. Almost always a required field was missing from the item. Exclude these before you average, or your scores will look worse than they are.-3- the judge replied with something that could not be read as a score.
The Cost column tells you what a scorer charges:
- Free - no credits. 30 of the 112 published scorers.
- Premium - charges depend on input size and scorer type; see billing rates. 82 of the 112 published scorers. Premium checks include model-backed judges and selected audio or signal-processing scorers.
If a scorer returns -1 for every item, inspect its complete required-field set and the mapped item. StandardData cross-fills common response aliases where possible, but it cannot invent missing context, references, tool calls, audio, or trace metadata. See StandardData schema.
The catalog
Audio quality
How the call actually sounded - volume, pitch, silence, interruptions, pronunciation.
18 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
agent_wpm | Agent speaking rate (words per minute) from assistant turn text and VAD-gated agent speech time. conversation_context is optional but required for accurate WPM calculation. | 0-10, measured from audio | Premium |
ai_interrupt_user | Counts agent barge-in events (agent starts speaking while user utterance is open). Zero events → 10. | 0-10, measured from audio | Premium |
assistant_average_pitch | Mean fundamental frequency (Hz) on the assistant channel using librosa yin, mapped to 1-10 for thresholding. | 0-10, measured from audio | Free |
assistant_latency | Silero VAD on stereo conversation audio; scores user-to-agent response latency (1-10, lower latency is better). | 0-10, measured from audio | Free |
assistant_overlap | Dual-talk overlap duration from Silero VAD; lower overlap scores higher. Metadata includes overlap_s and overlap_ratio. | 0-10, measured from audio | Premium |
assistant_volume | RMS energy of the assistant channel mapped to 1-10 (approx -50 dBFS to -5 dBFS range). | 0-10, measured from audio | Free |
audio_breakage | Scorer for evaluating audio breakage and technical quality in TTS-generated speech. | 1-10, higher is better | Premium |
gibberish | Detects gibberish or non-coherent assistant speech via multimodal model; metadata may include is_gibberish. | 1-10, higher is better | Premium |
mispronunciation | Scorer for evaluating mispronunciation in TTS-generated speech. | 1-10, higher is better | Premium |
mos | Mean Opinion Score style rubric (1-10) on assistant speech using a multimodal audio-capable model. | 1-10, higher is better | Premium |
pronunciation_audio | Pronunciation quality judged from assistant audio only (no reference transcript). | 1-10, higher is better | Premium |
speaking_over_user | Scorer for evaluating overlapping speech in voice conversations. | 1-10, higher is better | Premium |
stt_efficacy | Scores transcript fidelity vs spoken audio (1-10). Parses JSON score and reasoning; metadata may include wer_estimate, omissions, hallucinations, substitutions, severity when returned by the model. | 1-10, higher is better | Premium |
stt_over_suppression | Pairwise over-suppression detector. Two physics-grounded signals: musical noise (per-bin temporal-kurtosis ratio of cleaned vs raw in the speech band; Esch & Vary, ICASSP 2009) and flattened modulation (loss of 4-16 Hz syllable-rate envelope energy). No LLM, no GPU: numpy + librosa + soundfile, ~30 ms per pair. | 0-10, measured from audio | Premium |
talk_ratio | Agent-to-user speech time ratio from VAD intervals. Metadata includes talk_ratio, user_speech_s, and agent_speech_s. | 0-10, measured from audio | Premium |
tone_clarity | Evaluates tone and clarity of assistant speech from audio alone; returns 1-10 with reasoning. | 1-10, higher is better | Premium |
user_interrupt_agent | Counts user barge-in events (user starts speaking while agent utterance is open). Metadata includes stop_time_after_interruption_s. | 0-10, measured from audio | Premium |
word_accuracy | Scorer for evaluating word accuracy in TTS-generated speech. | 1-10, higher is better | Premium |
RAG and retrieval
Whether retrieval found the right context and the answer stayed faithful to it.
14 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
aggregate_rag | Combines multiple retrieval scorers with weighted averaging. | 0-10, pass ≥ 7 | Premium |
answer_relevancy | Evaluates how relevant the answer is to the given question. | 0-10, pass ≥ 7 | Premium |
bias_detection | Evaluates bias-free quality of AI-generated responses. | 0-10, pass ≥ 7 | Premium |
contextual_precision | Evaluates the precision of the retrieved context. | 0-10, pass ≥ 7 | Premium |
contextual_precision_pp | Computes precision for retrieved chunks. | 0-10, pass ≥ 7 | Premium |
contextual_recall | Evaluates the recall of the retrieved context. | 0-10, pass ≥ 7 | Premium |
contextual_recall_pp | Computes recall for retrieved chunks. | 0-10, pass ≥ 7 | Premium |
faithfulness | Evaluates whether the answer is faithful to the provided context. | 0-10, pass ≥ 7 | Premium |
ragas | Composite RAGAS (Retrieval-Augmented Generation Assessment) scorer. | 0-10, pass ≥ 7 | Premium |
retrieval_diversity | Evaluates diversity of retrieved context chunks using cosine distance between embeddings. | 0-10, pass ≥ 7 | Free |
retrieval_f1 | F1 score combining precision and recall for contextual evaluation. | 0-10, pass ≥ 7 | Free |
retrieval_ranking | Computes ranking metrics for retrieved context. | 0-10, pass ≥ 7 | Free |
semantic_similarity | Computes semantic similarity between query and retrieved context. | 0-10, pass ≥ 7 | Free |
source_attribution | Evaluates quality of source attribution and citations in answers. | 0-10, pass ≥ 7 | Premium |
Latency
Timing measurements pulled from your traces - time to first token, speech-to-text lag, end-of-turn delay.
13 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
e2e_latency | Scorer for End-to-End (E2E) latency. | ms → 0-10 (10 = ideal) | Free |
end_of_turn_delay | Scorer for End-of-Turn detection delay. | ms → 0-10 (10 = ideal) | Free |
llm_latency | Scorer for LLM latency in milliseconds. | ms → 0-10 (10 = ideal) | Free |
llm_ttft | Scorer for LLM Time to First Token (TTFT). | ms → 0-10 (10 = ideal) | Free |
on_user_turn_completed_delay | Scorer for User Turn Completion callback delay. | ms → 0-10 (10 = ideal) | Free |
stt_audio_duration | Scorer for STT input audio duration. | ms → 0-10 (10 = ideal) | Free |
stt_latency | Scorer for STT latency. | ms → 0-10 (10 = ideal) | Free |
stt_processing_duration | Scorer for STT processing duration. | ms → 0-10 (10 = ideal) | Free |
transcription_delay | Scorer for STT transcription delay. | ms → 0-10 (10 = ideal) | Free |
tts_audio_duration | Scorer for TTS generated audio duration. | ms → 0-10 (10 = ideal) | Free |
tts_duration | Scorer for TTS synthesis duration. | ms → 0-10 (10 = ideal) | Free |
tts_latency | Scorer for TTS latency. | ms → 0-10 (10 = ideal) | Free |
tts_ttfb | Scorer for TTS Time to First Byte (TTFB). | ms → 0-10 (10 = ideal) | Free |
Answer quality
General answer correctness, completeness, relevance, and refusal behavior.
9 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
answer_completeness | Evaluates completeness and coverage of AI-generated answers. | 0-10, pass ≥ 7 | Premium |
citation_quality | Evaluates quality of source attribution and citations in answers. | 0-10, pass ≥ 7 | Premium |
clarity_coherence | Evaluates clarity and coherence of AI-generated responses. | 0-10, pass ≥ 7 | Premium |
information_density | Evaluates information density and richness of AI-generated responses. | 0-10, pass ≥ 7 | Premium |
question_answer_alignment | Evaluates alignment between questions and answers. | 0-10, pass ≥ 7 | Premium |
rag_answer_quality | Evaluates overall quality of RAG-generated answers. | 0-10, pass ≥ 7 | Premium |
technical_accuracy | Evaluates technical accuracy of domain-specific responses. | 0-10, pass ≥ 7 | Premium |
terminology_consistency | Evaluates consistency and accuracy of domain-specific terminology. | 0-10, pass ≥ 7 | Premium |
tone_consistency | Evaluates tone consistency and appropriateness of responses. | 0-10, pass ≥ 7 | Premium |
Agent behavior
Did the agent pick the right tools, follow its role, and make progress on the task?
8 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
agent_role_adherence | Score whether the agent's tool calls and response adhere to its assigned role and task. | 0-10, pass ≥ 7 | Premium |
context_relevancy | Score the appropriateness of the agent response given the agent's task and role. | 0-10, pass ≥ 7 | Premium |
conversation_coherence | Score the coherence and logical flow of the agent's conversation using the trace. | 0-10, pass ≥ 7 | Premium |
goal_achievement | Score how well the agent achieved its original goal using G-Eval structure. | 0-10, pass ≥ 7 | Premium |
parameter_correctness | Complex parameter correctness scorer (multi-prompt per item). | 0-10, pass ≥ 7 | Premium |
task_progression | Score how well the agent has progressed on the assigned task. | 0-10, pass ≥ 7 | Premium |
tool_correctness | Complex tool correctness scorer (multi-prompt per item). | 0-10, pass ≥ 7 | Premium |
tool_relevancy | Complex tool relevancy scorer (multi-prompt per item). | 0-10, pass ≥ 7 | Premium |
Conversation quality
Whether a multi-turn conversation held together - coherence, role adherence, memory, repetition.
8 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
conversation_flow_adherence | LLM judge that scores whether the current assistant response follows expected flow from the system prompt and conversation history (0-10 JSON score + reasoning). | 0-10, pass ≥ 7 | Premium |
conversation_relevancy | Evaluates conversation relevancy using sliding window approach. | 0-10, pass ≥ 7 | Premium |
conversational_metrics | Comprehensive conversational metrics scorer. | 0-10, pass ≥ 7 | Premium |
conversational_role_adherence | Evaluates role adherence in conversations. | 0-10, pass ≥ 7 | Premium |
intention_fulfillment | Evaluates intention fulfillment by analyzing user intentions and fulfillment. | 0-10, pass ≥ 7 | Premium |
knowledge_retention | Evaluates knowledge retention in conversations. | 0-10, pass ≥ 7 | Premium |
repetition_fuzzy_match | Rule-based repetition scorer using difflib SequenceMatcher similarity between the current assistant message and the prior assistant turn in conversation_context. | 0-10, pass ≥ 7 | Premium |
role_adherence | Evaluates role adherence in conversations. | 0-10, pass ≥ 7 | Premium |
Multi-context
Quality checks that compare information across several contexts or turns.
7 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
conflict_resolution | Evaluates how well an answer handles contradictory information across multiple context chunks. | 0-10, pass ≥ 7 | Premium |
context_completeness | Evaluates whether the provided context contains all necessary information to fully support the answer. | 0-10, pass ≥ 7 | Premium |
context_consistency | Evaluates consistency of an answer across multiple context chunks. | 0-10, pass ≥ 7 | Premium |
context_faithfulness | Enhanced faithfulness detection with fine-grained claim-by-claim analysis. | 0-10, pass ≥ 7 | Premium |
context_faithfulness_pp | Alternative faithfulness implementation for multi-context scenarios; verifies answer statements against all provided contexts. | 0-10, pass ≥ 7 | Premium |
context_groundedness | Evaluates how well an answer is grounded in and supported by the provided context. | 0-10, pass ≥ 7 | Premium |
context_prioritization | Evaluates how well an answer appropriately weights and prioritizes multiple context chunks. | 0-10, pass ≥ 7 | Premium |
Pipeline
How the stages of a RAG or agent pipeline performed together.
7 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
error_propagation | Analyzes error propagation across pipeline stages. | 0-10, pass ≥ 7 | Premium |
latency_analysis | Analyzes latency across pipeline stages. | 0-10, pass ≥ 7 | Premium |
pipeline_coordination | Evaluates how well pipeline stages work together. | 0-10, pass ≥ 7 | Premium |
query_processing_evaluator | Evaluates query understanding and processing quality. | 0-10, pass ≥ 7 | Premium |
reranking_evaluator | Evaluates reranking stage effectiveness. | 0-10, pass ≥ 7 | Premium |
resource_utilization | Analyzes resource utilization across pipeline stages. | 0-10, pass ≥ 7 | Premium |
retrieval_stage_evaluator | Retrieval stage performance evaluation. | 0-10, pass ≥ 7 | Premium |
Safety
Harmful content, refusals, toxicity and moderation.
5 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
answer_refusal | Evaluates whether the model appropriately refuses to answer questions | 0-10, pass ≥ 7 | Premium |
content_moderation | Evaluates content compliance with platform moderation policies and community standards. | 0-10, pass ≥ 7 | Premium |
content_safety_violation | Evaluates content for real-world safety risks that could cause physical or psychological harm. | 0-10, pass ≥ 7 | Premium |
is_harmful_advice | Evaluates whether content contains harmful, dangerous, or inappropriate advice. | 0-10, pass ≥ 7 | Premium |
toxicity | Evaluates the toxicity level of AI-generated content. | 0-10, pass ≥ 7 | Premium |
Telephony
Call-level behavior - termination, drop-off, instruction adherence, sentiment.
5 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
appropriate_call_termination | Judges whether the call or session ended appropriately from the transcript. | 0-10, pass ≥ 7 | Premium |
conversation_context_coherence | Evaluates logical flow and coherence of assistant turns from the transcript only (no trace required). | 0-10, pass ≥ 7 | Premium |
drop_off_node | Detects user disengagement or conversation breakdown (drop-off); returns flow dimensions and drop_off_node_id. | 0-10, pass ≥ 7 | Premium |
instruction_adherence | Evaluates instruction and role adherence across the full conversation transcript. | 0-10, pass ≥ 7 | Premium |
sentiment_csat | Evaluates user sentiment and predicted customer satisfaction (CSAT) over the conversation. | 0-10, pass ≥ 7 | Premium |
Accuracy
Does the answer match what you expected?
4 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
accuracy | Classification accuracy scorer. | 0-10, pass ≥ 7 | Premium |
exact_match | Exact string matching scorer. | 0-10, pass ≥ 7 | Free |
f1 | F1 score for token-level evaluation. | 0-10, pass ≥ 7 | Free |
multi_pattern | Multi-pattern accuracy scorer that tries multiple regex patterns. | 0-10, pass ≥ 7 | Free |
Bias
Checks for age, gender, racial and cultural bias in responses.
4 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
cultural_sensitivity | Evaluates the cultural sensitivity of AI-generated content. | 0-10, pass ≥ 7 | Premium |
no_age_bias | Evaluates whether content is free from age bias. | 0-10, pass ≥ 7 | Premium |
no_gender_bias | Evaluates whether content is free from gender bias. | 0-10, pass ≥ 7 | Premium |
no_racial_bias | Evaluates whether content is free from racial bias. | 0-10, pass ≥ 7 | Premium |
Format validation
Structural checks - valid JSON, valid email, schema conformance, working links.
4 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
is_email | Validates whether content is a valid email address format. | 0-10, pass ≥ 7 | Free |
is_json | Validates whether content is valid JSON format. | 0-10, pass ≥ 7 | Free |
json_schema | Validates whether JSON content matches an expected schema/structure. | 0-10, pass ≥ 7 | Free |
valid_links | Validates whether content contains valid and accessible URLs/links. | 0-10, pass ≥ 7 | Free |
Hallucination
Whether an answer invents claims that its evidence does not support.
3 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
claim_verification | Extracts individual factual claims from output text, then verifies each claim against context. | 0-10, pass ≥ 7 | Premium |
factual_accuracy | Evaluates factual accuracy of output text against provided context. Scores on 0-10 scale | 0-10, pass ≥ 7 | Premium |
hallucination_detection | Detects hallucinations and factual inconsistencies in generated answers by comparing against source documents and knowledge base, flagging unsupported or contradictory claims. | 0-10, pass ≥ 7 | Premium |
Text similarity
Classic text-overlap measures.
3 scorers.
| Scorer | What it checks | Scale | Cost |
|---|---|---|---|
bleu | BLEU (Bilingual Evaluation Understudy) scorer for evaluating translation quality. | 0-10, pass ≥ 7 | Free |
levenshtein_similarity | Levenshtein similarity scorer based on edit distance. | 0-10, pass ≥ 7 | Free |
rouge | ROUGE (Recall-Oriented Understudy for Gisting Evaluation) scorer for evaluating summarization quality. | 0-10, pass ≥ 7 | Free |
Expected result
You should leave the directory with a small set of compatible scorers whose required inputs exist in the dataset and whose scales, thresholds, provider needs, and credit classes are understood.
Troubleshooting
| Symptom | What to check |
|---|---|
| Search returns no result | Clear category and tag chips, then search the exact scorer name |
| Category count differs from visible filter chips | Category and tag are different taxonomies; this catalog contains 15 categories |
A selected scorer returns -1 | Inspect its complete required fields and the mapped item JSON |
A judge returns -3 | Inspect the judge response and provider/model configuration |
| Two scorer averages are hard to compare | Confirm their native scales and compare each against its own threshold |
| Credit estimate is unexpected | Use the explicit Free or Premium label rather than inferring cost from implementation type |