Noveum AI vs Langfuse: which LLM observability platform fits your team?
A detailed comparison of observability tools for AI engineers focused on evaluation, monitoring, and review workflows.
Best for automated evaluation at scale and NovaPilot reports that recommend what to investigate next

Best for open-source flexibility and for teams that want full control over their own observability stack
“We recently switched from Langfuse to Noveum AIfor our DarGlobal team, and the experience has been very positive. The Noveumteam helped us integrate directly into our existing codebase, which made onboarding much smoother. Compared to Langfuse, maintenance and deployment overhead dropped significantly, saving engineering effort and operational cost.
The biggest workflow improvement was AI-assisted debugging. We used to manually dig through logs, copy tracesinto Claude Code, and iterate from there. With Noveum, we analyze spans and tracesinside the platform and identify issues in place, which has saved a lot of debuggingtime. AI-based scorer recommendations also removed the guesswork of which scorers to build and configure. When we needed CrewAI, the team implemented it quickly and helped us integrate it properly. Shivam and the broader team have been responsive throughout, proactive on our feedback, and helpful in suggesting code changes when needed. Overall, the platform has streamlined our AI observability and debuggingwhile reducing operational overhead.”

Rehan Hussain Imam
Senior AI consultant, DarGlobal
Which tool is right for you?
Both connect traces and evaluations; their packaged workflows differ.
Langfuse excels when engineers want open-source building blocks and full hosting choice. Noveum connects tracing with dataset-based evaluations and NovaPilot reports. NovaPilot analyzes evaluated items and recommends next steps; engineers still review the findings, implement changes, and validate them.

Langfuse was not included in Noveum's June 2026 vendor-run benchmark, so this page makes no benchmark-based performance claim about Langfuse. Compare both products with your own representative traces, datasets, evaluators, and deployment requirements.
The details that actually matter
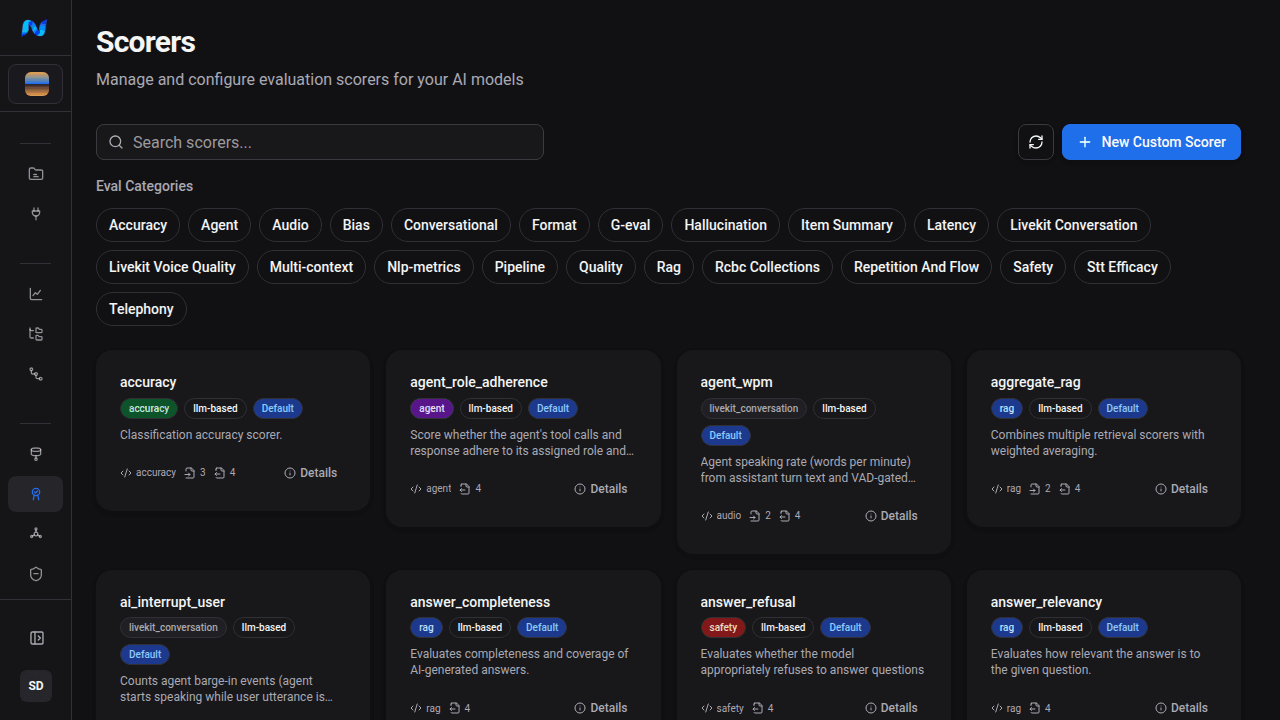
Managed checks with reviewable results.
NovaEval publishes 112 scorers across 15 categories and applies only the selected compatible checks to configured dataset items. Langfuse offers managed LLM-as-judge and code evaluators plus self-hosted evaluation workflows; compare scorer fit, output, and cost on your own dataset.
Learn about scorers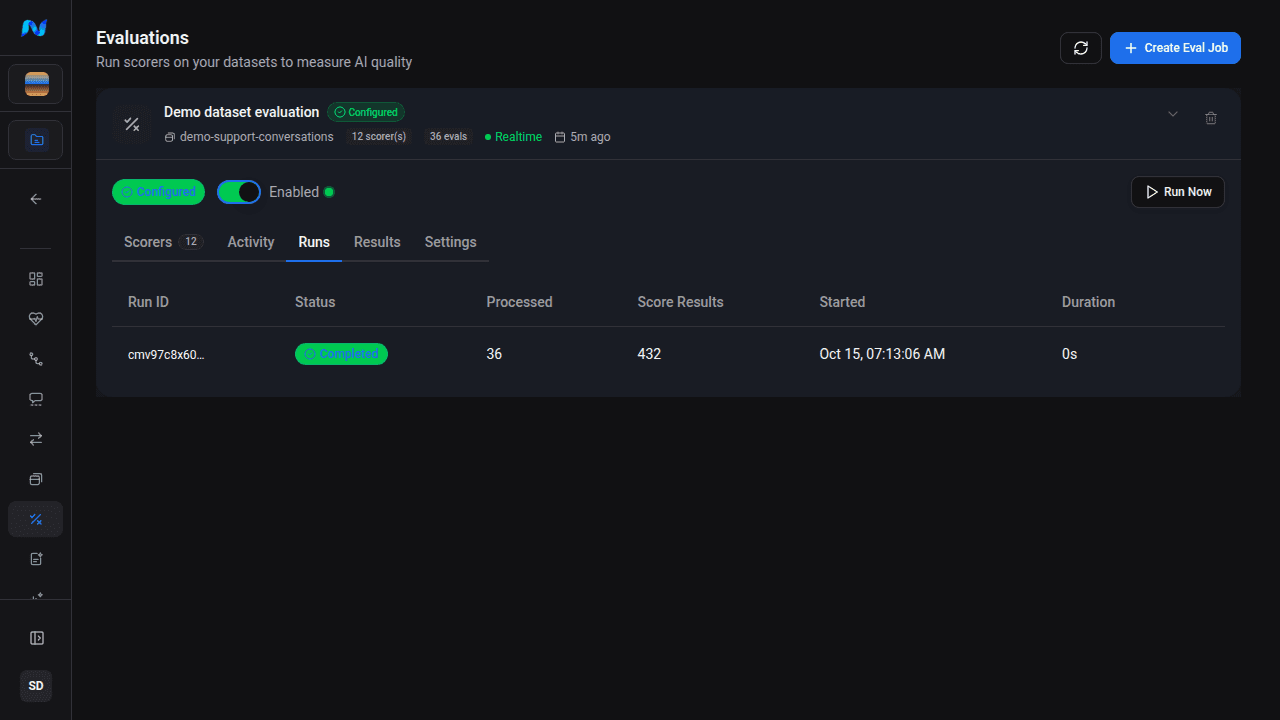
Reference-free options when the required inputs fit.
Noveum can turn selected production traces into dataset items through a reviewed ETL mapper, and many compatible scorers do not require expected answers. Langfuse supports datasets, experiments, production evaluations, and annotation workflows. Test both mapping paths with representative data.
Learn about evaluation framework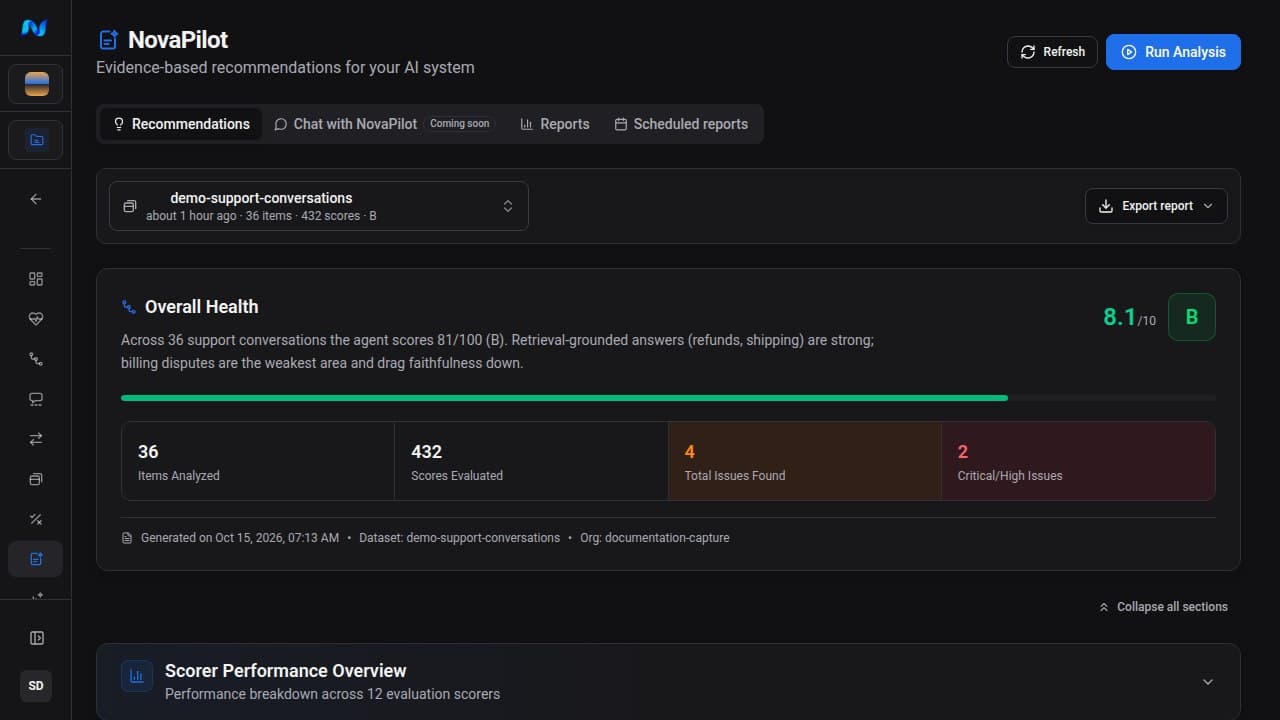
Turn evaluation results into a reviewable plan
NovaPilot analyzes evaluated dataset items and organizes issue patterns and recommended next steps into a report. Your engineers review the evidence, decide what to change, and validate the result in a separate evaluation run.
See how NovaPilot worksWealthink
“We've used Noveumduring the early stages of our retrievalpipeline at Wealthink, and what stood out most was how proactively the team helped us evaluate output quality.
They ran a custom evalon our setup and surfaced inaccuracies in our retrievallayer that we were later able to independently validate.
That genuinely helped us diagnose issues faster.
The foundersthemselves regularly jump on calls with our team to debug problems and discuss what should be built next.
That level of involvement isn't easy at this stage, and you can feel it reflected in the product. The tracingcapabilities and overall UI have improved noticeably over the months we've been using it.
If you're integrating AI into your tech stack and care about catching failures before your users do, it's definitely worth checking out.”

Umang Joshi
Founder, Wealthink
Pricing posture
Observation-based pricing
More eval power, less spend
With Noveum, credits pay for evaluation and analysis while spans and audio or image attachment storage have separate allowances. Smart Sampling controls which eligible items enter evaluation as traffic grows. The 112 published scorers and custom scorers reduce the number of checks teams must build from scratch, while NovaPilot reports organize recurring failures into recommendations.
Common questions
Common questions
Is Noveum AI open source?
Noveum AI's platform is proprietary. The first-party `noveum-trace` Python tracing SDK is open source and available on GitHub and PyPI; that does not make the hosted platform or NovaEval product open source.
How long does integration take?
Start by instrumenting one representative operation with Noveum's Python SDK or a supported framework integration, then verify the first ingested trace in the dashboard. In Noveum's June 2026 vendor-run benchmark, the importer parsed 100 raw traces into 440 per-turn items without operator field mapping. For a production workflow, review, test, and save the ETL mapping before enabling it.
Can I self-host Noveum?
Noveum can scope in-VPC deployment for qualifying enterprise engagements; architecture, managed dependencies, and data flows depend on the agreement. If open-source self-hosting is a requirement, compare Langfuse's current license and deployment path with Noveum's proprietary enterprise options.
How is credit-based pricing different from observation-based?
Noveum charges by credit for compute-heavy activities: one Premium scorer applied to one eligible dataset item costs 1 credit, NovaSynth voice calls cost 25 credits per minute, text conversations cost 10 credits, and NovaPilot analysis costs 3 credits per analyzed dataset item. Raw trace capture uses separate plan allowances. Langfuse charges per observation unit, so its usage model differs.
Can I migrate from Langfuse to Noveum?
Yes. You can run Noveum instrumentation alongside an existing observability setup while validating trace shape, payload policy, and project metadata. Evaluation output formats differ, so test the Noveum ETL mapping and scorer compatibility on a small cohort before switching a production workflow.
How does Noveum's scoring accuracy compare to other evaluation platforms?
Langfuse was not included in Noveum's June 2026 vendor-run benchmark, so those results cannot support a direct Noveum-versus-Langfuse accuracy or latency claim. Run the same representative dataset and evaluation criteria through both products before deciding.
Our take
For teams shipping AI agents to real users, Noveum combines a library of 112 published scorers, configurable trace sampling, enterprise custom scorers, SIP and phone-capable NovaSynth testing, and NovaPilot recommendation reports. Langfuse was not included in Noveum's vendor-run benchmark, so validate both products on your own workload.
Langfuse is a solid open-source platform for developers who want to self-host and build their own eval stack. The MIT license and active community are real strengths. Noveum is designed for teams that want managed evaluation plus NovaPilot analysis reports, while retaining engineering review for any change.
Next step
Put your agents in the loop
Production AI agents your customers can trust.
Trusted in production by enterprise and high-growth teams