112 scorers, 15 categories
Choose compatible checks for hallucination, RAG quality, answer correctness, tool use, coherence, and safety. The library includes 82 Premium and 30 Free scorers.
Evaluation
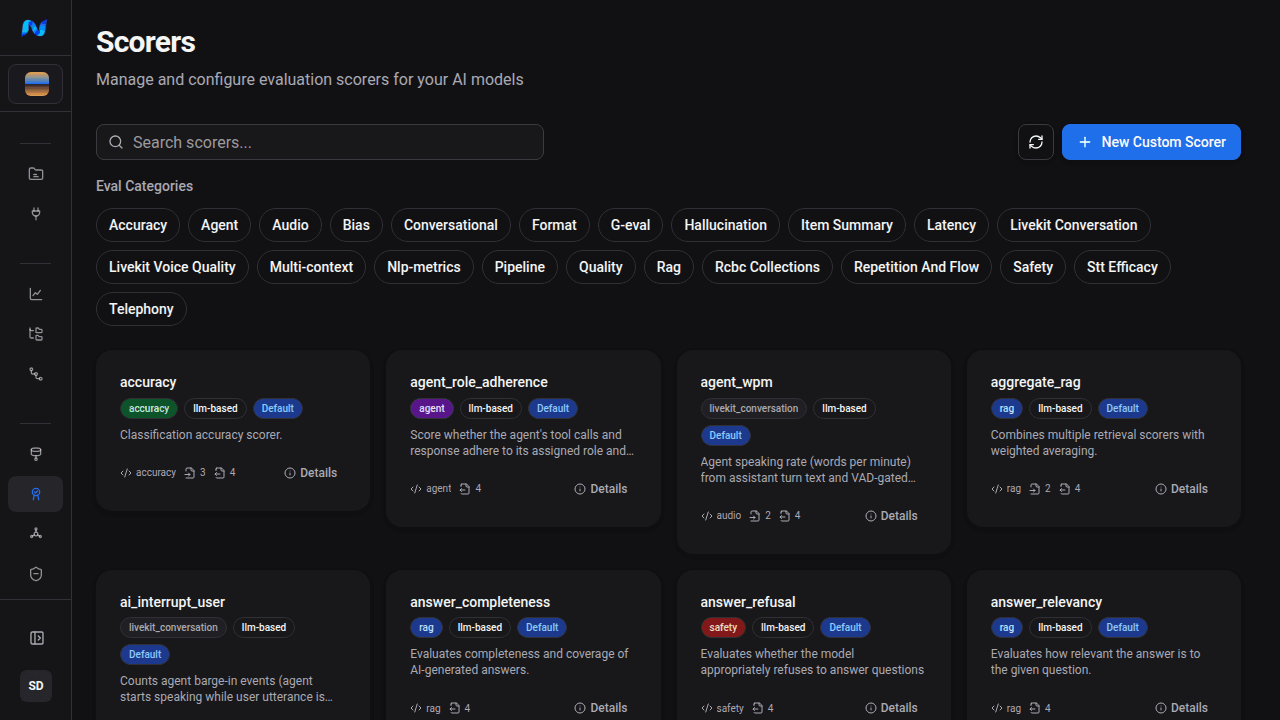
NovaEval applies selected compatible scorers to configured dataset items. Its library has 112 published scorers across 15 categories, including 76 model-backed and 36 dedicated voice and audio scorers, plus rubric-based custom scorers.
112
published scorers
15
scorer categories
36
dedicated voice scorers
01: Capabilities
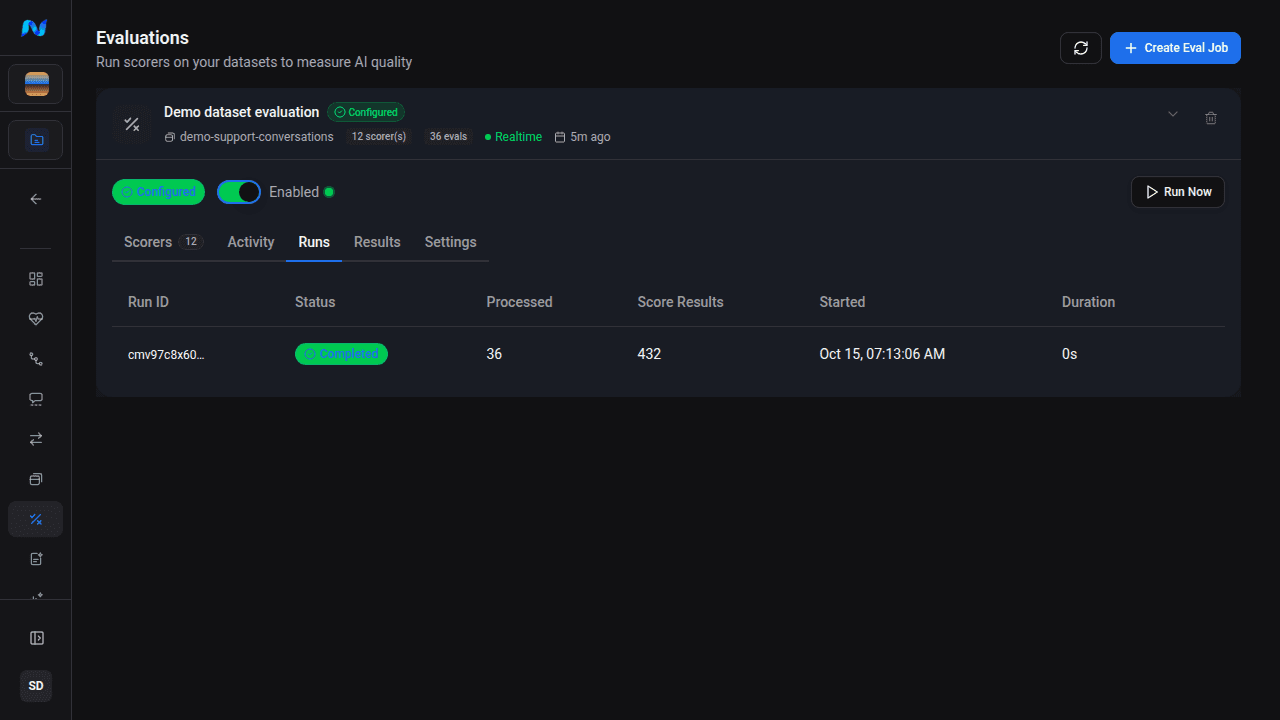
Choose compatible checks for hallucination, RAG quality, answer correctness, tool use, coherence, and safety. The library includes 82 Premium and 30 Free scorers.
36 dedicated voice scorers: mispronunciation, audio breakage, word error rate, talk-ratio, barge-in, dead-air, and full STT / LLM / TTS pipeline latency.
Choose the provider and model used by compatible LLM-backed scorers. Their results can include reasoning so teams can inspect how a verdict was produced.
Turn product requirements into instruction-driven scorers with templated placeholders such as input_text, output_text, expected_output, retrieved_context, and tool_calls. The separate scorer recommender can suggest compatible published scorers from sampled data.
A reviewed, tested, and saved ETL mapper converts eligible traces into versioned dataset items. Enable the job only after the mapped fields match the intended evaluation.
Keep the scorer, provider, model, prompt, and threshold fixed when comparing agent versions so results stay like-for-like.
02: The library
NovaEval preserves each scorer’s native output - numeric scores, booleans, or labels - with reasoning where the scorer provides it.
03: Under the hood
112 published scorers, including 76 model-backed and 36 voice and audio checks, plus template-driven custom criteria and ETL-generated datasets. Model-backed results can include judge reasoning.
Scorer library
112 published scorers across 15 categories - hallucination, RAG quality, answer correctness, tool use, coherence, safety, bias, format validation, and more.
Voice & audio suite
36 dedicated voice scorers: mispronunciation, audio breakage, word error rate (WER), talk-ratio, barge-in, dead-air, and STT / LLM / TTS pipeline latency: signals a transcript never shows.
Provider & model controls
Compatible model-backed scorers let you choose the judge provider and model for an evaluation job, making the evaluation setup explicit.
Custom scorers
Instruction-driven scorers with templated placeholders: input_text, output_text, expected_output, retrieved_context, tool_calls, and more: turn your product requirements into evaluation criteria.
Scorer output
Scorers preserve their native numeric, boolean, or label output, plus pass state and structured metadata. Model-backed judges can also return free-text reasoning.
Datasets from traffic
An AI Mapper can propose how selected traces become dataset items. Review, test, and save the mapping before an enabled ETL job processes eligible traffic.
The loop
Evaluation supplies evidence for the rest of the platform: NovaPilot analyzes configured results, while NovaGuard stores separate spend and traffic policies for a connected runtime to enforce.
Trusted in production by enterprise and high-growth teams