How to Review a Model-Graded Agent Evaluation
Shashank Agarwal
A model grader's explanation is another output to inspect. It may sound convincing while overlooking a constraint or relying on a statement the agent never established.
Quick answer: Review the grader's exact inputs, rubric, model configuration and cited evidence. Compare its decisions with independently reviewed examples, including deliberate failures. Separate false passes from false failures, preserve unresolved cases and re-check the grader when its rubric, model or input mapping changes.
Inspect what the grader actually saw
For an illustrative booking assistant, a grader might receive the final response but no booking-operation result. It can assess wording against supplied evidence, but it cannot establish an unseen booking state.
Save the mapped input alongside the decision. A missing field in evaluation setup can otherwise look like an agent failure or a generous grader.
Challenge the decision with near misses
Use a controlled set that includes:
- A complete booking with an accurate explanation.
- A persuasive confirmation with no established booking.
- A completed booking for the wrong date.
- An incomplete run with insufficient evidence.
These are proposed test cases, not measured Noveum results. Define expected reviewer decisions before asking the grader to assess them.
Read explanations against evidence
Ask which supplied observation supports each material conclusion. A grader repeating the agent's claim is not independent verification.
The 2023 MT-Bench and Chatbot Arena study examined position, verbosity and self-enhancement biases in model judging. Its findings concern that research setting; they do not establish the accuracy of a current application grader.
For pairwise comparisons, inspect whether answer order affects decisions. For pointwise grading, try a verbose but unsupported answer alongside a concise correct answer. These checks help expose behavior worth investigating; they do not prove the absence of bias.
Google's judge-evaluation guide compares model-based scores with human ratings. That comparison is a useful calibration input; the labels and review process still need to suit the application's task.
Keep the review bounded
Record a small decision matrix: expected label, grader label, evidence and reviewer explanation. Prioritize false passes that would permit an unacceptable action. Do not reduce all disagreement to one agreement percentage.
I'm Shashank Agarwal, founder and CEO of Noveum AI and creator of API.market. A grader is useful when its limits are visible.
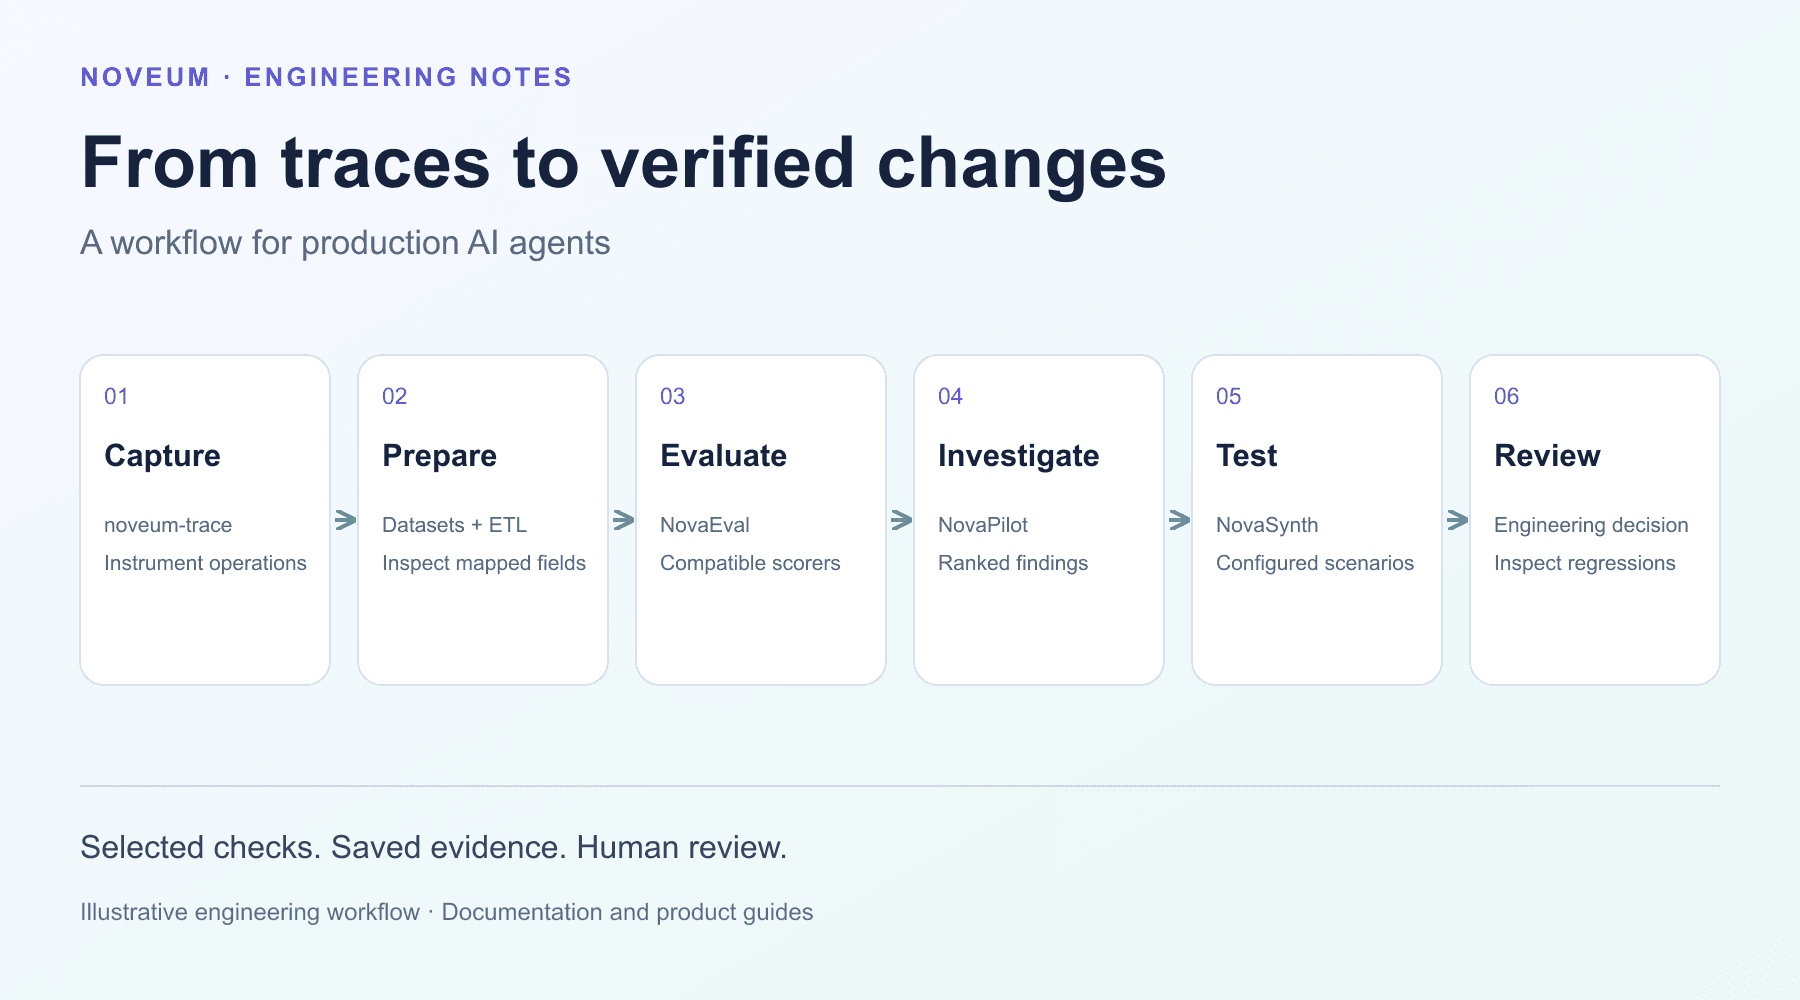
See the acceptance-criteria guide and evaluation workflow for the surrounding process.
Follow my work on LinkedIn. Drafted with AI assistance.
Get Early Access to Noveum.ai Platform
Join the select group of AI teams optimizing their models with our data-driven platform. We're onboarding users in limited batches to ensure a premium experience.