Compare Two Agent Runs Without Pretending They Are Identical
Shashank Agarwal
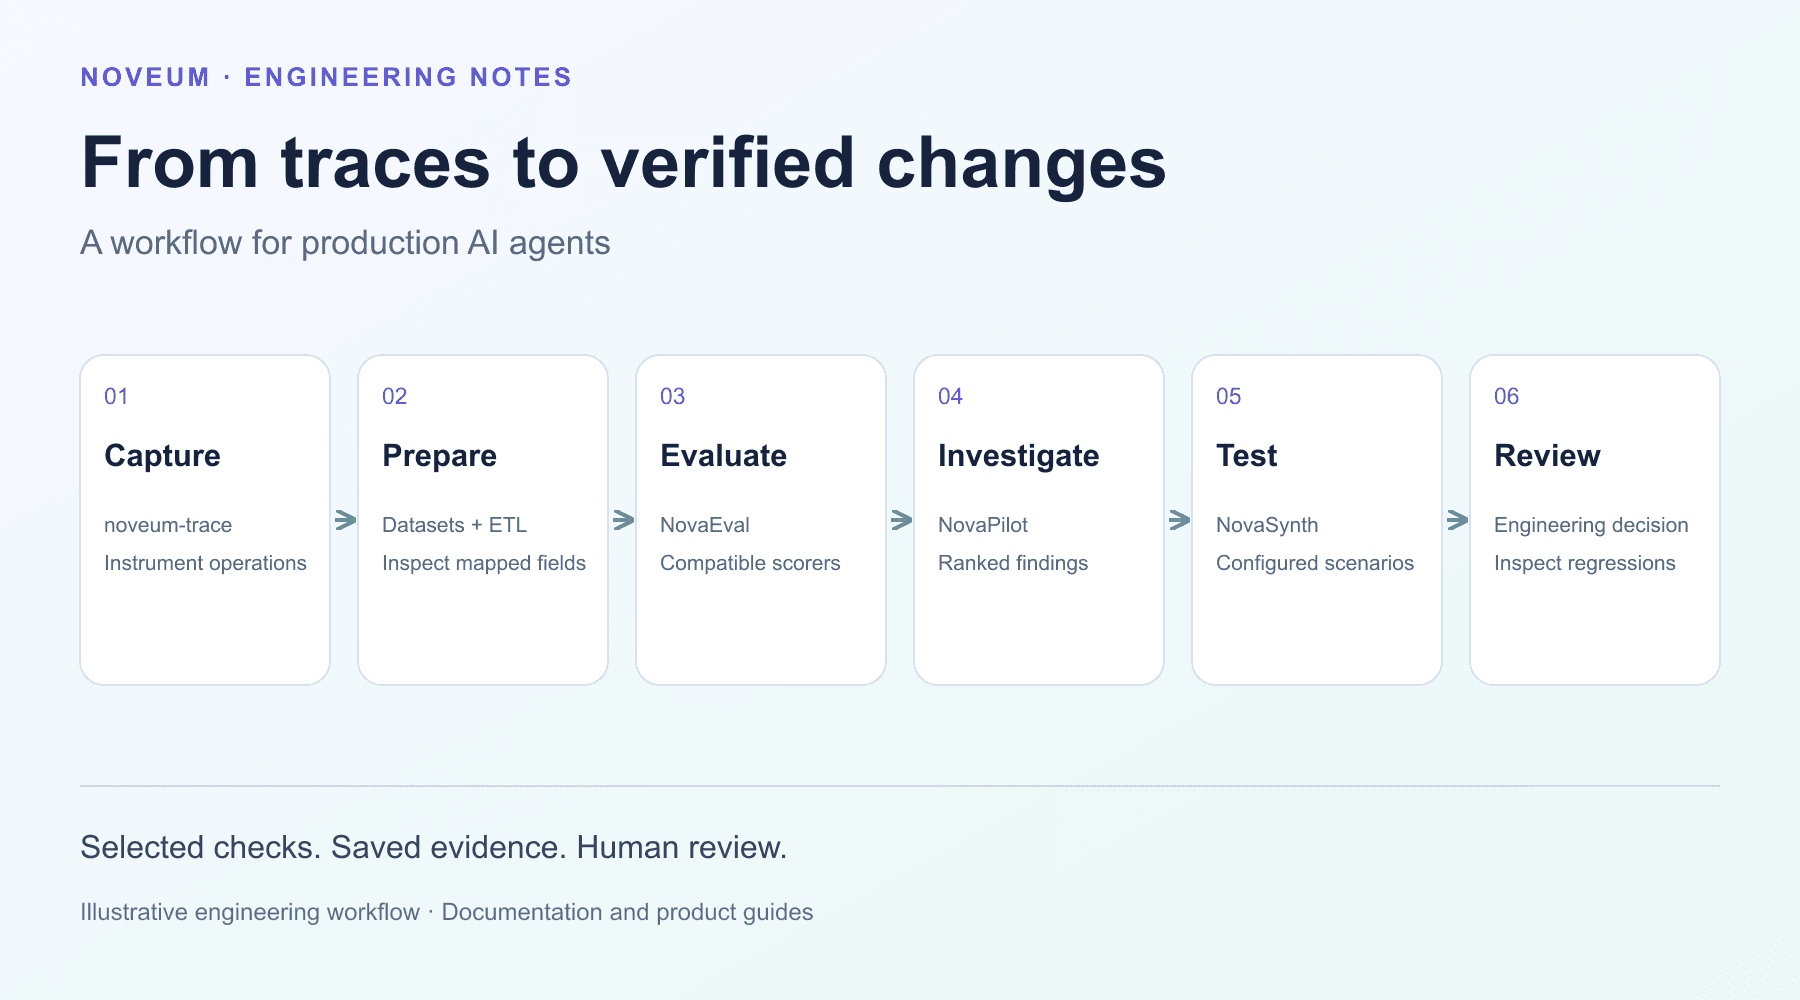
Two runs can share a user prompt and still differ in source data, tool responses, execution timing or evaluator configuration. Those differences affect what a comparison can establish.
Quick answer: Compare agent and environment versions alongside inputs, fixtures and evaluator settings. Fix controllable conditions, retain repeated attempts and label remaining variability. Attribute a result to the tested configuration unless a narrower experiment isolates the component being changed.
Write the comparison question
For an illustrative search assistant, the question might be whether a revised selection rule chooses the requested document revision. If the source index also changed, a passing candidate run cannot by itself isolate the selection rule's effect.
Record the observed improvement, then describe the changed conditions explicitly.
Use a comparison record
| Dimension | Baseline and candidate record |
|---|---|
| Input | Exact task and relevant conversation |
| Agent | Code, prompt and model configuration |
| Evidence | Source fixture and retrieved material |
| Tools | Contract and controlled responses |
| Evaluation | Rubric and grader versions |
| Execution | Attempts, failures and missing observations |
This proposed record helps another reviewer understand comparability. It is not a claim that identical configuration makes a probabilistic system deterministic.
Keep attempts visible
Do not select one attractive candidate response and compare it with one unattractive baseline response. Preserve the attempts used in the decision and explain how they were chosen.
If a dependency remains live, identify what changed or could have changed. A fixture can improve control, but its result may apply more narrowly than a production observation.
State the conclusion at the right scope
“The candidate passed the revision-selection case under the controlled source fixture” is a bounded statement. “The model is now reliable” requires much broader evidence.
Use the comparison to choose a next action: expand relevant cases, inspect a recurring failure or test the change under additional conditions. A small experiment is useful when it answers its actual question.
I'm Shashank Agarwal, founder and CEO of Noveum AI and creator of API.market. These are proposed engineering methods and illustrative fixtures, not measured customer results.
Use the tool-boundary guide for operation evidence and the regression-test guide for controlled verification.
Follow my work on LinkedIn. Drafted with AI assistance.
Get Early Access to Noveum.ai Platform
Join the select group of AI teams optimizing their models with our data-driven platform. We're onboarding users in limited batches to ensure a premium experience.