Build a Regression Set for a Voice Prompt Change
Shashank Agarwal
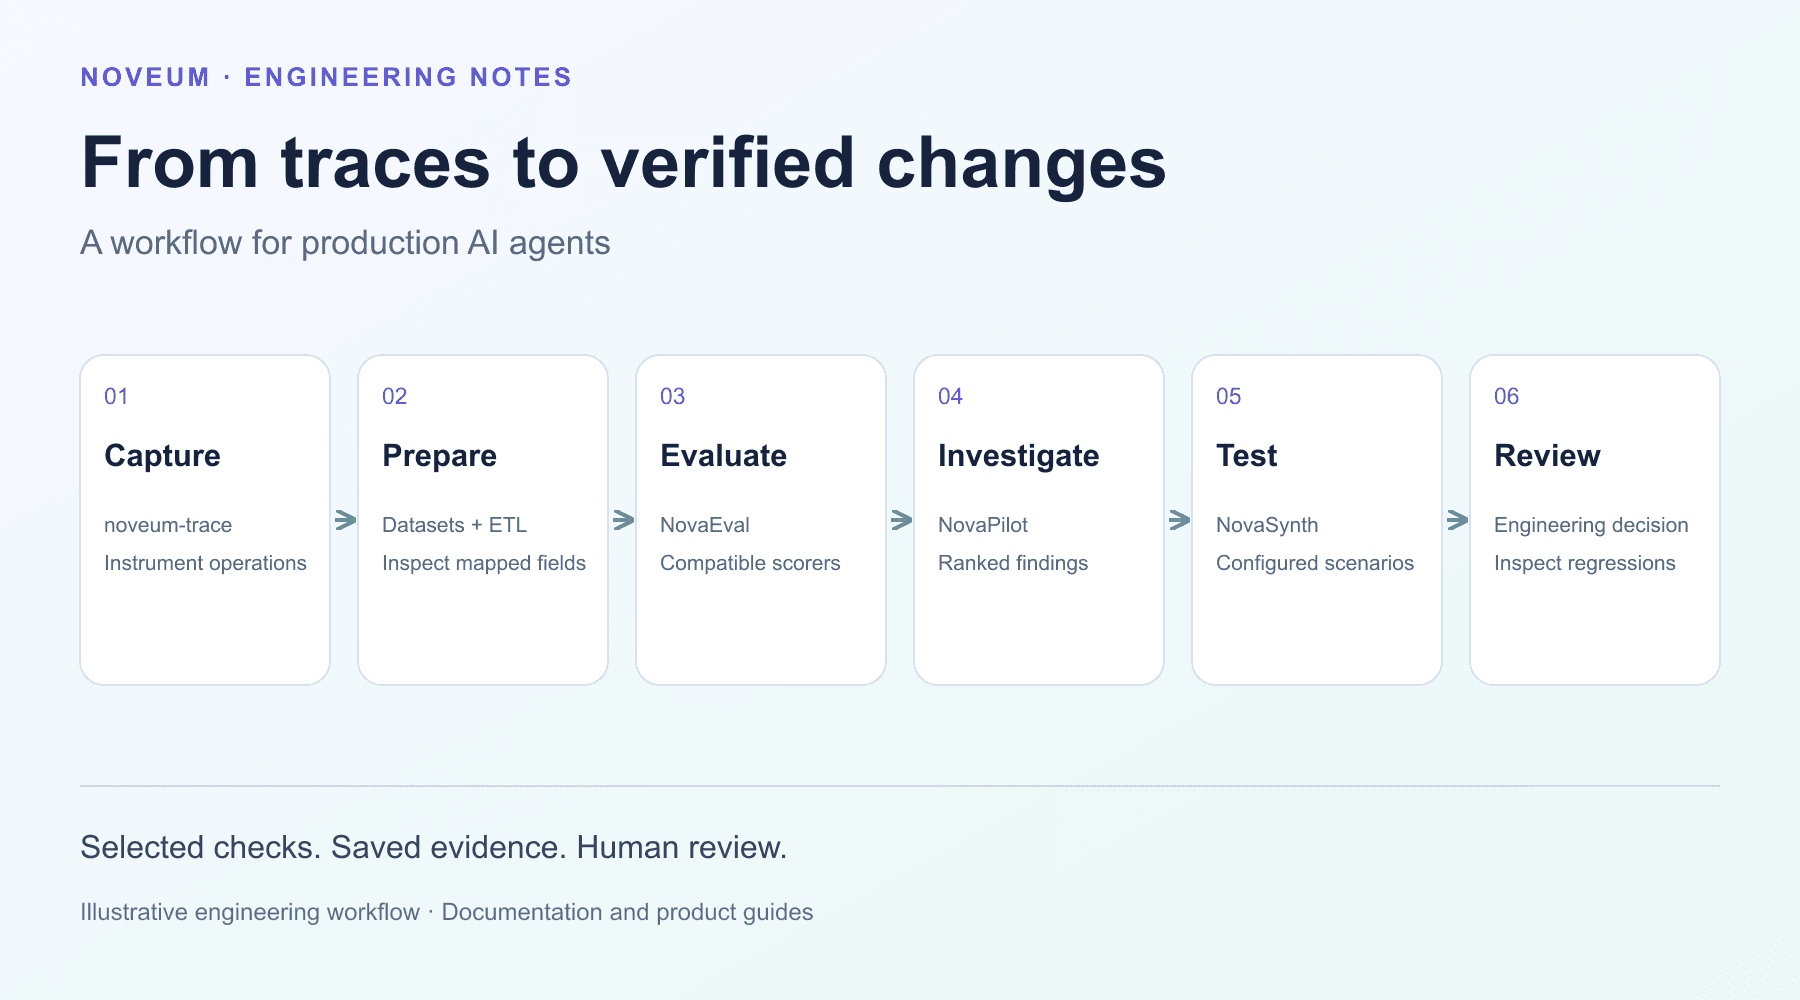
A voice prompt change can improve one exchange while making another harder to complete. A regression set should preserve the task conditions that matter, not just replay the demo that inspired the change.
Quick answer: Keep representative goals, known failures and relevant boundary cases under recorded configurations. Compare candidate and baseline outcomes while identifying changes in audio, transport, tools and fixtures. Review task completion, unsupported claims and turn handling separately.
Start from the intended correction
Suppose an illustrative service agent repeatedly asks for information the caller already supplied. A candidate prompt asks it to check available context before repeating a question.
The regression set should include a caller who supplied the information, a caller who has not supplied it and a case where the earlier information is ambiguous. Otherwise a rule that suppresses every follow-up question could appear to fix the problem.
Preserve the comparison conditions
| Record | Reason to retain it |
|---|---|
| Agent and prompt version | Identifies the behavior being compared |
| Caller and scenario configuration | Defines the task and communication behavior |
| Tool and backend fixture | Keeps relevant external state interpretable |
| Audio and transport conditions | Helps distinguish conversational changes from execution differences |
| Evaluation setup | Makes judgments comparable |
| Run outcome and missing evidence | Preserves failed and unavailable results |
Use synthetic or appropriately approved data. This proposed record is not a universal product schema.
Do not make one replay a guarantee
Voice interactions can vary. A single pass on a selected recording does not establish that every live caller will have the same experience. Choose a stated comparison method and preserve all relevant runs, including regressions.
If the candidate changes a model or a voice setting as well as the prompt, record that explicitly. The result then concerns the combined change, not necessarily the wording alone.
Review the failure paths too
Include unavailable information, failed tools, a caller correcting a value and an interrupted response where relevant. Define what the agent should do rather than rewarding a fluent continuation regardless of the task.
Inspect some passing cases. A judge that fails to notice repeated questions can make a regression look like an improvement.
I’m Shashank Agarwal, founder and CEO of Noveum AI and creator of API.market. NovaSynth provides configured scenario testing; engineers still interpret the comparison and decide whether to release a candidate.
The starter dataset guide covers selection, while the repeatable-failure guide explains controlled fixtures.
Follow my work on LinkedIn. Drafted with AI assistance.
Get Early Access to Noveum.ai Platform
Join the select group of AI teams optimizing their models with our data-driven platform. We're onboarding users in limited batches to ensure a premium experience.